GPU platform
Discuss NVIDIA H100, H200 or A100 configurations with our team. The proposed model and configuration are subject to availability.
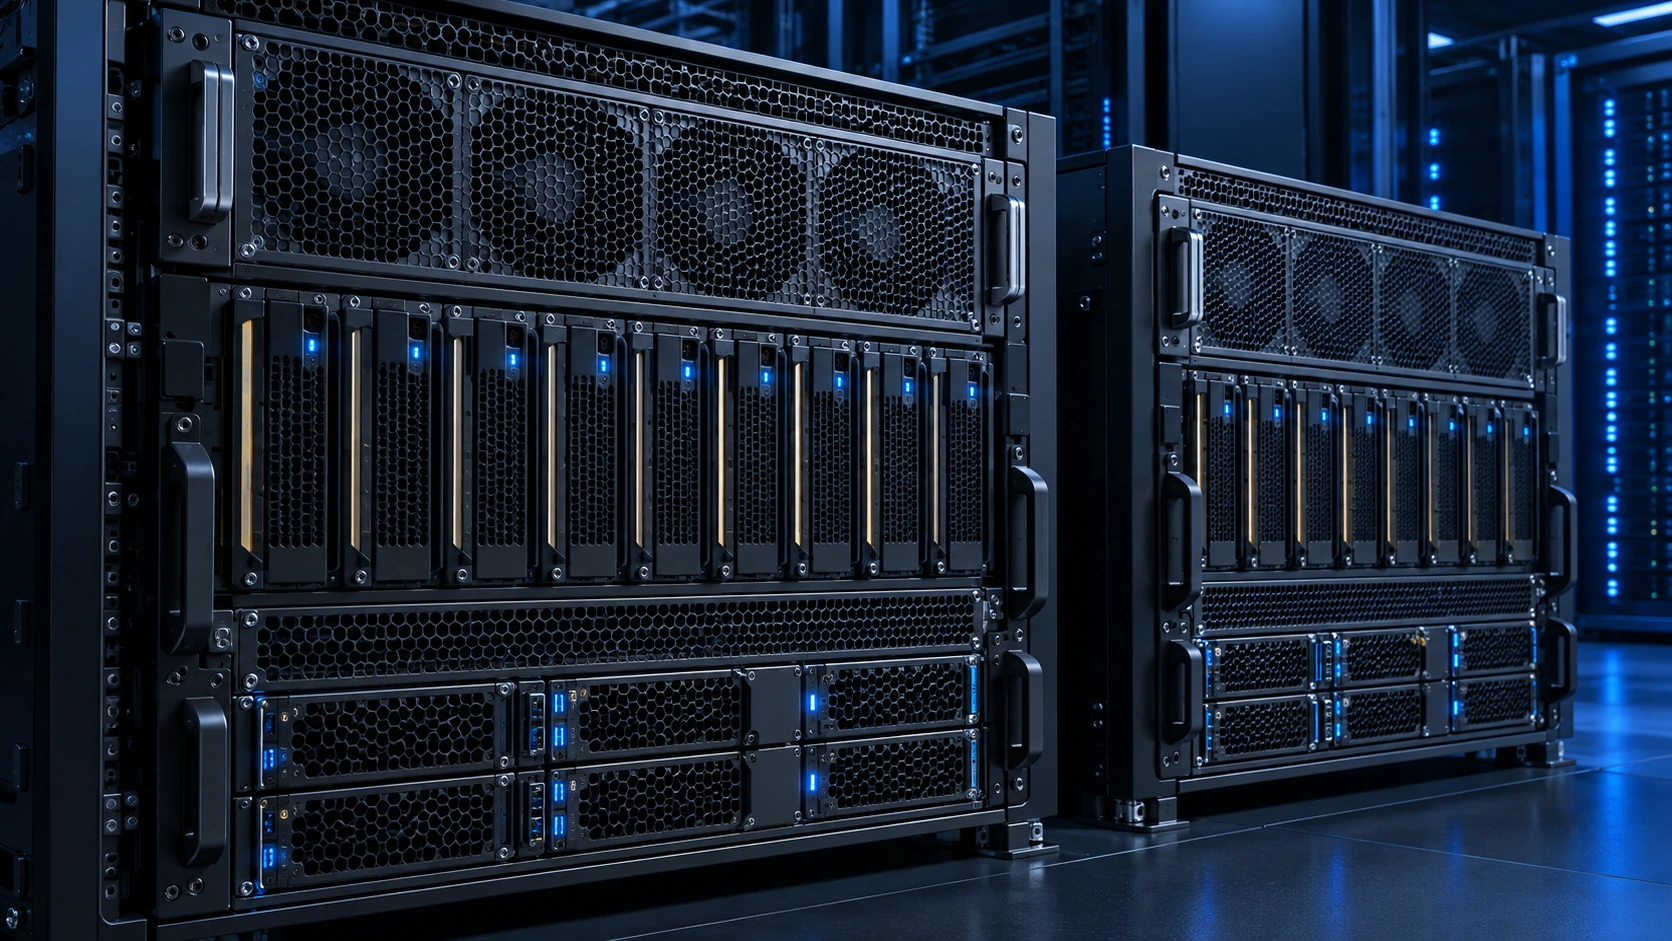
Dedicated GPU servers and AI infrastructure for training, fine-tuning, inference and high-performance computing. Configure an environment built around your performance, memory and scalability requirements.
From large language models and generative AI to computer vision, inference and HPC, we configure GPU infrastructure around your compute, GPU memory, storage and networking requirements.
Get a QuoteGPU server configurations based on NVIDIA platforms, including H100, H200 and A100, subject to availability.
Single- and multi-GPU servers configured around your workload, performance and scalability requirements.
GPU compute combined with high-speed networking and storage to support data-intensive AI and HPC workloads.
Our infrastructure team helps with configuration, deployment and ongoing support as your AI workloads evolve.
Start with workload requirements, then confirm the hardware configuration and availability with our team.
Discuss NVIDIA H100, H200 or A100 configurations with our team. The proposed model and configuration are subject to availability.
Share model size, precision, context length and batch size so GPU memory requirements can be assessed for training or inference.
Plan GPU count alongside workload parallelism, communication between GPUs and expected growth. Final sizing depends on your application.
Size compute and GPU memory around your model, datasets, batch size and training approach.
Plan for response time, throughput and concurrent requests when serving trained models.
Account for model size, context length and input or output data when planning text and generative workloads.
Match GPU compute and data delivery to image resolution, video streams and processing volume.
Review application compatibility, numerical precision and data movement for GPU-accelerated computing.
Assess traffic between servers, storage and GPUs alongside bandwidth and latency requirements. Network design should reflect how the workload is distributed.
Learn More →Plan capacity and read/write performance for datasets, model weights and checkpoints. Include data protection and retention requirements in the brief.
Learn More →Balance CPU, system memory and GPU resources around preprocessing, data loading and application needs.
Learn More →Share your models, datasets, performance targets, software requirements and growth plans.
Review GPU, memory, CPU, storage and networking choices, subject to hardware availability.
Agree the deployment scope, responsibilities and validation criteria before the environment is handed over.
Choose the management and support scope your team needs as workloads evolve.
Discuss H100, H200 and A100 configurations with our team. Hardware availability and the final configuration must be confirmed in your proposal.
Yes. Share the model, expected request volume, context length and response-time targets so the configuration can be planned around your inference workload.
There is no single configuration for every model. Sizing depends on model size, precision, batch size, training or inference, and how the application distributes work.
Software installation is not assumed to be included. Specify your operating system, drivers, frameworks and containers so the deployment responsibilities and scope can be agreed.
Include your use case, model and dataset sizes, preferred GPU platform, memory needs, storage, connectivity, support requirements and target timeline.
Share your workload and infrastructure requirements so we can prepare a configuration proposal.